Machine Learning and AI Are Related, but They Are Not Interchangeable
Artificial intelligence is the larger ambition of making computer systems perform tasks that appear to require judgment, perception, language, planning, or adaptation. Machine learning is one powerful way to pursue that ambition: instead of specifying every decision in advance, developers give an algorithm examples and a method for improving from those examples. The distinction sounds academic until you choose a course, evaluate a product, or plan a project. Calling every automated feature “machine learning” hides important questions about how it works, while treating AI as a single technology makes the field seem more mysterious than it is. A useful beginner explanation therefore starts with scope, then examines evidence. AI describes the goal or behavior; machine learning describes a family of data-driven methods that may produce that behavior. Some AI systems learn from data, some rely mainly on explicit rules or search, and many real products combine all three.
Why the Vocabulary Matters Outside a Classroom
Imagine a customer-support tool that routes a message to the billing team. One version might scan for a fixed list of words such as “invoice” and “refund.” Another might use a classifier trained on thousands of previously routed messages. Both can support an intelligent-looking outcome, but only the second example necessarily uses machine learning. The difference affects maintenance. A rules-based system changes when a person edits the rules; a learned classifier changes when its training data, model, or decision threshold changes.
That distinction also changes the questions a responsible buyer should ask. For a fixed-rule system, you want to know who wrote the rules, how conflicts are resolved, and what happens when an input does not match. For a machine-learning system, you also need information about training examples, evaluation data, error rates, drift, and monitoring. Precise language helps you investigate the mechanism instead of accepting “AI-powered” as a complete explanation.
Think of AI as the Goal and Machine Learning as One Route
The field of AI predates today’s data-hungry models. Researchers have long built systems that search possible moves, apply symbolic logic, solve constrained plans, or represent expert knowledge. A chess program can explore future positions and select a move through search. A scheduling system can satisfy explicit constraints about rooms, instructors, and times. These systems may count as AI because they perform reasoning or planning tasks, even if they never improve by studying historical examples.
Machine learning takes a different route. A learning algorithm searches for useful patterns in examples. Given photographs paired with category labels, it may adjust internal parameters until it can classify unseen photographs reasonably well. Given past sales and contextual variables, it may estimate future demand. The resulting model is not a list of human-readable rules. It is a learned mathematical relationship whose behavior must be measured on data that was not used to fit it.
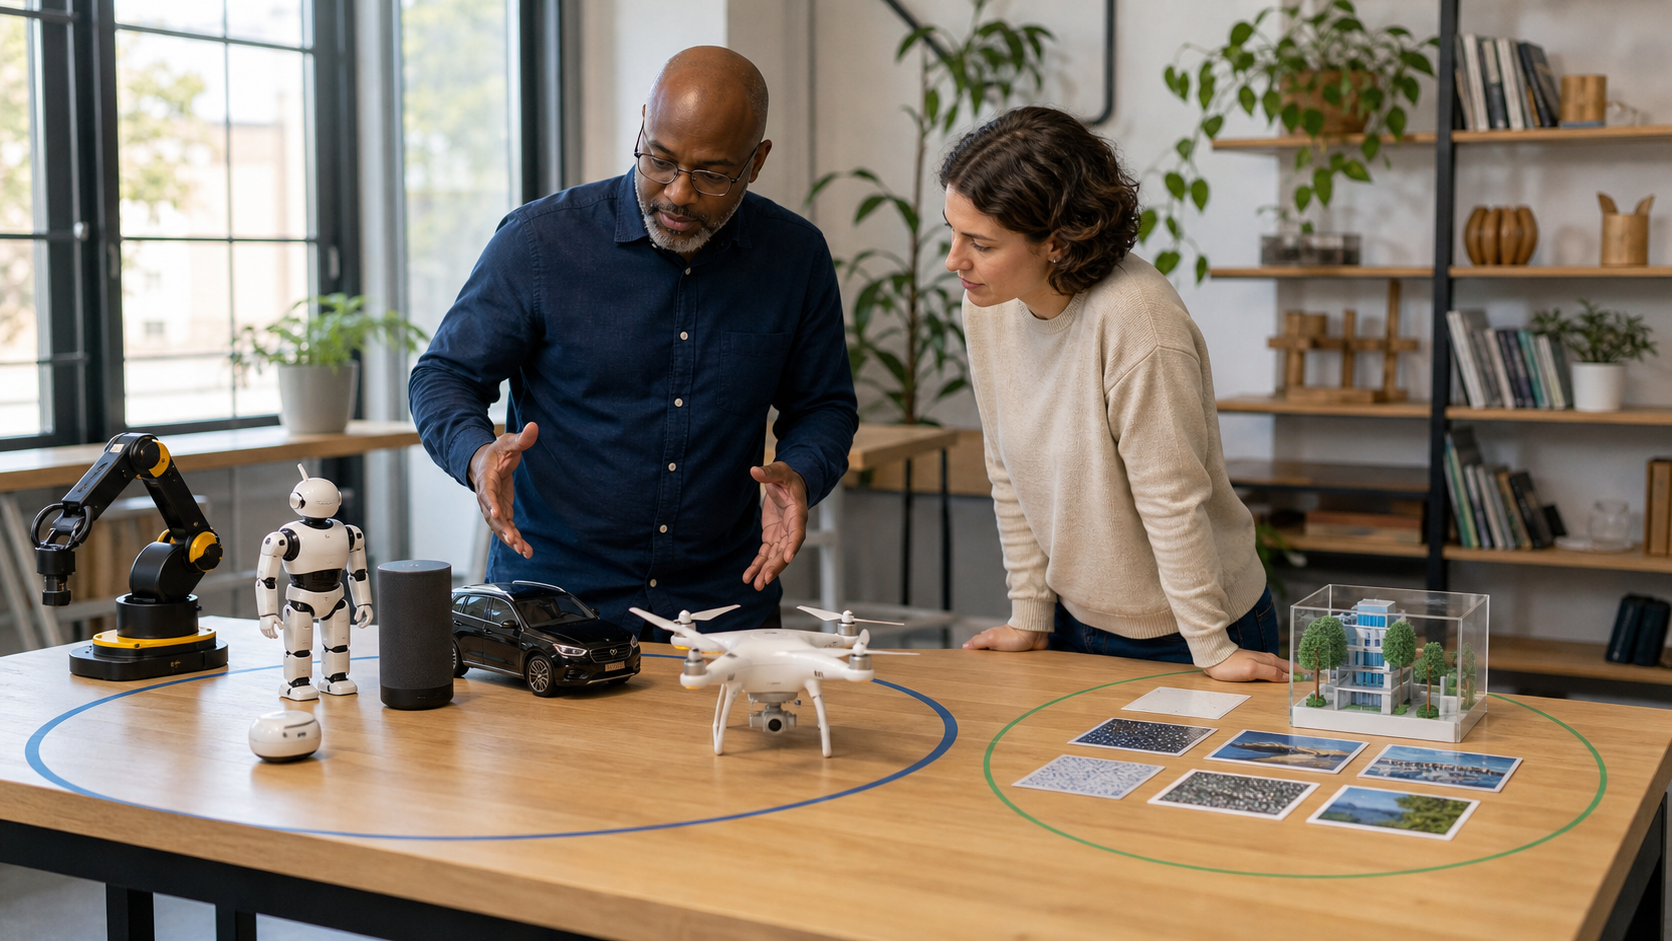
The nesting is therefore simple: machine learning sits inside artificial intelligence, but AI extends beyond machine learning. The boundary is not perfectly tidy because products are assembled from components. A navigation application might use learned traffic predictions, a hand-designed routing algorithm, business rules, and a conventional interface. Asking whether the whole product “is machine learning” is less informative than asking which components learn from data and which components follow programmed logic.
Programmed Rules Behave Differently from Learned Patterns
Explicit rules are attractive when the policy is stable, the conditions are clear, and exceptions can be described. A payroll calculation, for example, should follow governing rules rather than infer what employees are likely owed. Rules can be inspected directly and may be easier to justify. Their weakness appears when the relevant patterns are too numerous or subtle to enumerate. Writing a complete set of rules for recognizing every ordinary way a person can phrase a request quickly becomes unmanageable.
Machine learning is useful when examples contain patterns that are difficult to encode by hand. It can recognize variations, rank possibilities, and make estimates under uncertainty. That flexibility has a cost. A model may inherit gaps or distortions from its data, fail on unfamiliar cases, or produce a confident result without a transparent reason. Learning does not eliminate human decisions; it moves many of them into data selection, objective design, evaluation, thresholds, and deployment policy.
What “Learning” Actually Means in Machine Learning
A machine-learning model does not learn like a person who understands a lesson and connects it to lived experience. Training is an optimization process. The system makes an output, compares that output with a target or objective, and adjusts internal values to reduce some measure of error. Repeating that process across many examples can produce a model that generalizes, meaning it performs usefully on relevant cases it did not see during training.
Different learning settings use different kinds of feedback. In supervised learning, examples include target answers, such as whether a transaction was fraudulent. In unsupervised learning, the system looks for structure without those labels, perhaps grouping customers with similar behavior. Reinforcement learning uses rewards connected to sequences of actions. These categories describe how an algorithm receives a learning signal; they do not tell you whether the final application is safe, fair, or valuable.
Evaluation determines whether training created something useful. Accuracy alone may be misleading when one outcome is rare or when different errors carry different costs. A medical screening system that misses a condition creates a different harm from one that flags too many healthy patients. A beginner should learn to ask which mistakes matter, how performance was measured, whether the test cases represent actual use, and what happens after the model encounters changing conditions.
Examples That Reveal the Difference
A household thermostat illustrates the spectrum. A basic programmable thermostat follows a schedule and fixed temperature thresholds. A more advanced system may predict occupancy from sensor history and adjust heating based on learned patterns. Both automate climate control, but the predictive feature is the machine-learning component. The physical controls, safety limits, and scheduling logic remain conventional software. Consider email filtering. A simple filter that moves every message containing a chosen phrase is a user-defined rule. A spam classifier trained on many examples is machine learning. The complete email service may also use AI-adjacent capabilities such as suggested replies, message summarization, and anomaly detection. Each feature can use a different model and a different evaluation standard. Treating the service as one invisible AI obscures those separate mechanisms and risks. Generative assistants provide another useful example. A large language model is trained through machine learning, and the surrounding assistant is an AI application. Yet the application normally includes non-learning components: retrieval systems fetch documents, filters enforce policies, software calls external tools, and deterministic code formats results. The fluent model receives the attention, but the reliability of the product often depends just as heavily on this surrounding engineering.
How the Distinction Guides a First Project
If your goal is to automate a small decision, begin by asking whether a dependable rule already describes it. A rule-based prototype can expose the workflow and create a baseline. Suppose you want to organize personal receipts. Start with explicit categories and keyword rules, measure where they fail, and only then consider training a classifier. The comparison teaches more than immediately importing a complex model because you can see what learning adds.
If variations make rules brittle, a machine-learning approach may be appropriate. Define the input, desired output, source of examples, and evaluation method before choosing an algorithm. Keep a separate test set and compare the model with a simple baseline. A model that is technically sophisticated but barely improves on a clear rule may not justify its added opacity, cost, or maintenance burden.
Common Misunderstandings to Leave Behind
Machine learning is not a program that rewrites itself freely after every interaction. Many deployed models remain fixed until a controlled retraining process occurs. Continuous learning is possible, but it introduces serious monitoring and safety challenges. When a product says it “learns from you,” the phrase may refer to personalization rules, stored preferences, aggregated future training data, or real-time model updates. Those are different practices and deserve separate explanations.
AI is also not defined by whether a system is conscious, humanlike, or universally intelligent. Most deployed systems are narrow: they perform a bounded task within an engineered environment. A vision model can identify objects without knowing why the objects matter. A planning system can optimize a route without understanding the traveler’s life. Humanlike language can encourage people to attribute broader understanding than evaluation supports.
Finally, using data does not automatically make software machine learning. Conventional programs read databases, calculate statistics, and display trends without fitting a model. The key question is whether examples are used to estimate a pattern or decision function rather than merely being stored, retrieved, or processed through specified instructions. That question will not settle every edge case, but it is a strong beginner test.
A Learning Sequence That Keeps the Concepts Clear
Start by collecting ten familiar product features and describe each in terms of input, process, and output. Mark which processes appear rule-based, which appear learned, and which probably combine methods. You will not always know from the outside, so record uncertainty instead of guessing. The exercise develops the habit of decomposing an AI claim into testable components.
Next, build one tiny rule system and one tiny learned system for comparable tasks. You might write rules that classify short messages, then train a simple classifier on labeled examples. Compare failure cases, update effort, and explanations. Follow that project with basic study of supervised learning, datasets, validation, and metrics. The goal is not to memorize every AI branch; it is to understand why a team would choose one method and what evidence should support that choice.
Questions Beginners Often Ask
Is generative AI the same as machine learning? Generative models are built with machine-learning methods, but generative AI is a category of applications and model behavior. Machine learning also includes many systems that classify, rank, forecast, detect anomalies, or recommend items without generating new text, images, or audio.
Does every machine-learning model use a neural network? No. Linear regression, decision trees, random forests, support vector machines, and many other methods can learn from data without deep neural networks. The appropriate choice depends on the data, objective, interpretability needs, performance constraints, and available expertise.
Which subject should a beginner study first? Learn the broad AI landscape briefly, then focus on machine-learning fundamentals if you want to build data-driven models. This order provides context without turning “AI” into an endless survey. People focused on product use, policy, or organizational adoption can instead emphasize evaluation and responsible application before technical implementation.
What is the shortest accurate explanation? Artificial intelligence is the broad field of creating systems that perform tasks associated with intelligence. Machine learning is a subset of AI in which algorithms fit patterns from examples. The definition is short, but good judgment comes from identifying the actual mechanism, evidence, and limits in a real system. When terminology feels uncertain, describe what goes in, how behavior changes, and what comes out; that concrete description is usually more useful than a fashionable label.